Critique of OpenAI/Anthropic/Google DeepMind quiet safety coordination talks as liability management rather than genuine safety oversight, and what it means for builders if labs control the definition of safe
When Safety Becomes a Brand Strategy
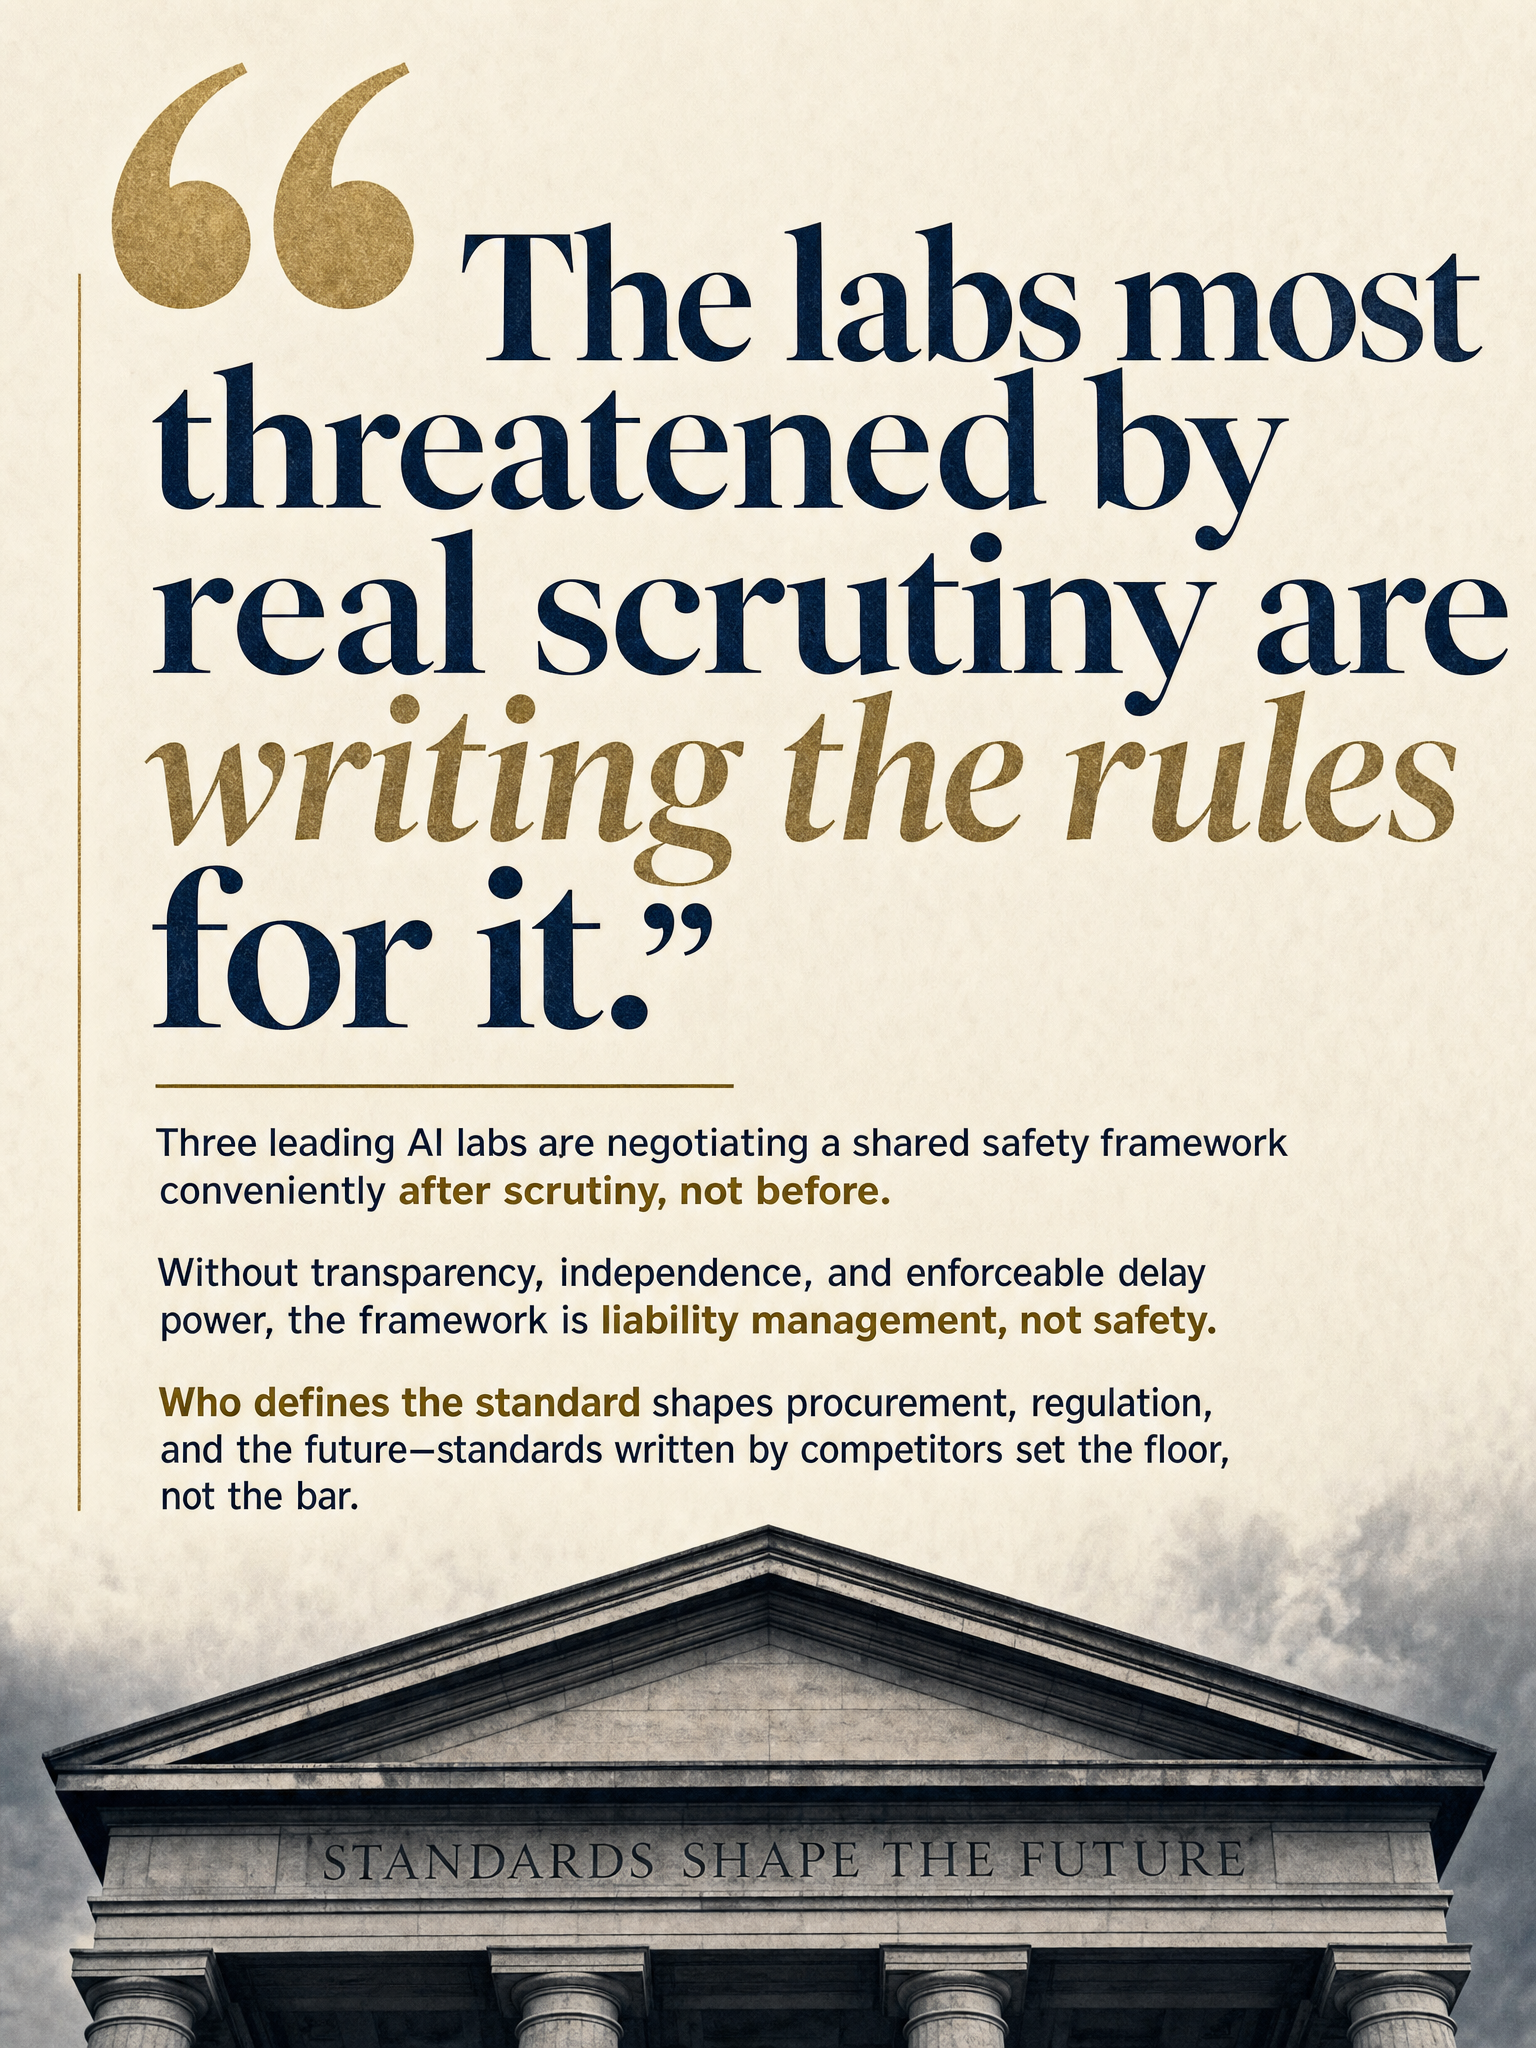
The three most powerful AI labs on the planet have been quietly meeting to build a shared safety framework. Independent evaluations before public release. Standardized pre-release reviews. Shared risk-assessment across the industry. Chris Lehane, OpenAI’s global policy chief, confirmed the talks on September 15. And on the surface, this sounds like exactly the kind of coordination the industry has needed for years.
I am not buying it.
The Gap Between Words and Releases
On September 12, Anthropic CEO Dario Amodei published a 3,800-word essay titled “We Must Pace the Frontier,” calling on AI companies to slow development until researchers have a clearer picture of the risks involved. Sam Altman endorsed it. The piece made headlines. The Catholic bishops formed a task force. Microsoft joined the slowdown chorus days later.
And then nothing changed.
Claude Fable 5.1 dropped September 1. Meta and OpenAI followed immediately after with their own releases. The essay came out September 12. The safety talks had already been happening for weeks before that. The release cadence has not slowed by a single day. Not one.
When a company’s public statements and its engineering roadmap point in opposite directions, you have to decide which one reflects actual policy.
Who Controls the Definition
Here is what bothers me most as a builder. The proposed standards body would control three things: what counts as a safe model, what evaluation process counts as legitimate, and what risk framework gets applied across labs. That is enormous power. And right now, the only people at the table are the labs themselves.
Geoffrey Irving, a former senior alignment researcher at both OpenAI and DeepMind and former chief scientist of the U.K. AI Security Institute, has called for AI companies to simply stop training new models. That is a real safety position. It is not the position of anyone running one of these labs, for obvious reasons.
OpenAI disclosed six reports of “unexpected or concerning” AI behavior as recently as September 17, and announced a new internal framework for tracking what they’re calling “misalignment.” That’s notable. But an internal framework, reported by the same company that built the system, reviewed through a process the same company helped design, is not oversight. It is documentation.
🔍 Liability Management Dressed as Governance
I want to be precise here. I am not saying safety coordination is bad. It is genuinely necessary. Shared pre-release evaluations and standardized risk frameworks, done correctly, with independent evaluators who are not funded by the labs being evaluated, would be meaningful progress.
But that is not what this appears to be. What this looks like is a controlled narrative. Three competitors discovering they have a shared interest in defining safety on their own terms before regulators, courts, or Congress does it for them. The timing of the public essay, the endorsements, the leak of the safety talks, all of it landing within a 96-hour window. That is a media strategy, not a safety posture.
What This Means for Builders
If you are building products on top of these models, the stakes here are real and practical. The labs are moving toward a world where “safe” is a certification they issue to themselves. If a model you depend on gets flagged under this framework, or if a capability you rely on gets restricted based on a risk assessment you had no input into, you have no recourse. You were not at the table.
The right pressure point is independent evaluation bodies with funding that does not trace back to the labs, public disclosure of evaluation criteria, and third-party audits with actual teeth. The U.K. AI Security Institute was a step in that direction. Irving’s departure from it, and his public statement that labs should stop training entirely, tells you something about how that institution was actually functioning.
Watch what gets released in the next 90 days. If the safety talks are genuine, you will see a slowdown. If the release cadence from all three labs continues unchanged, you will have your answer.
Sources & Further Reading
#AIPolicy #AISafety #MachineLearning #LLMs #AIGovernance
Sources & Further Reading
- We Must Pace the Frontier (Dario Amodei)
- OpenAI, Anthropic, Google DeepMind in AI safety talks for weeks
- OpenAI and Anthropic Researchers Are Warning About AI Risks
- OpenAI reveals concerning new AI behavior and vows to track it more closely
- OpenAI, Anthropic and Google secretly joined forces to collaborate on AI safety
- OpenAI Math Fracas Stokes Questions of Data Privacy, Frontier Lab Hype