Mystery model ‘Gestalt’ appears on Contra Frontier Design benchmark outperforming Claude Fable 5.2 by 200 points with no known attribution
Gestalt Is the Model Nobody Announced
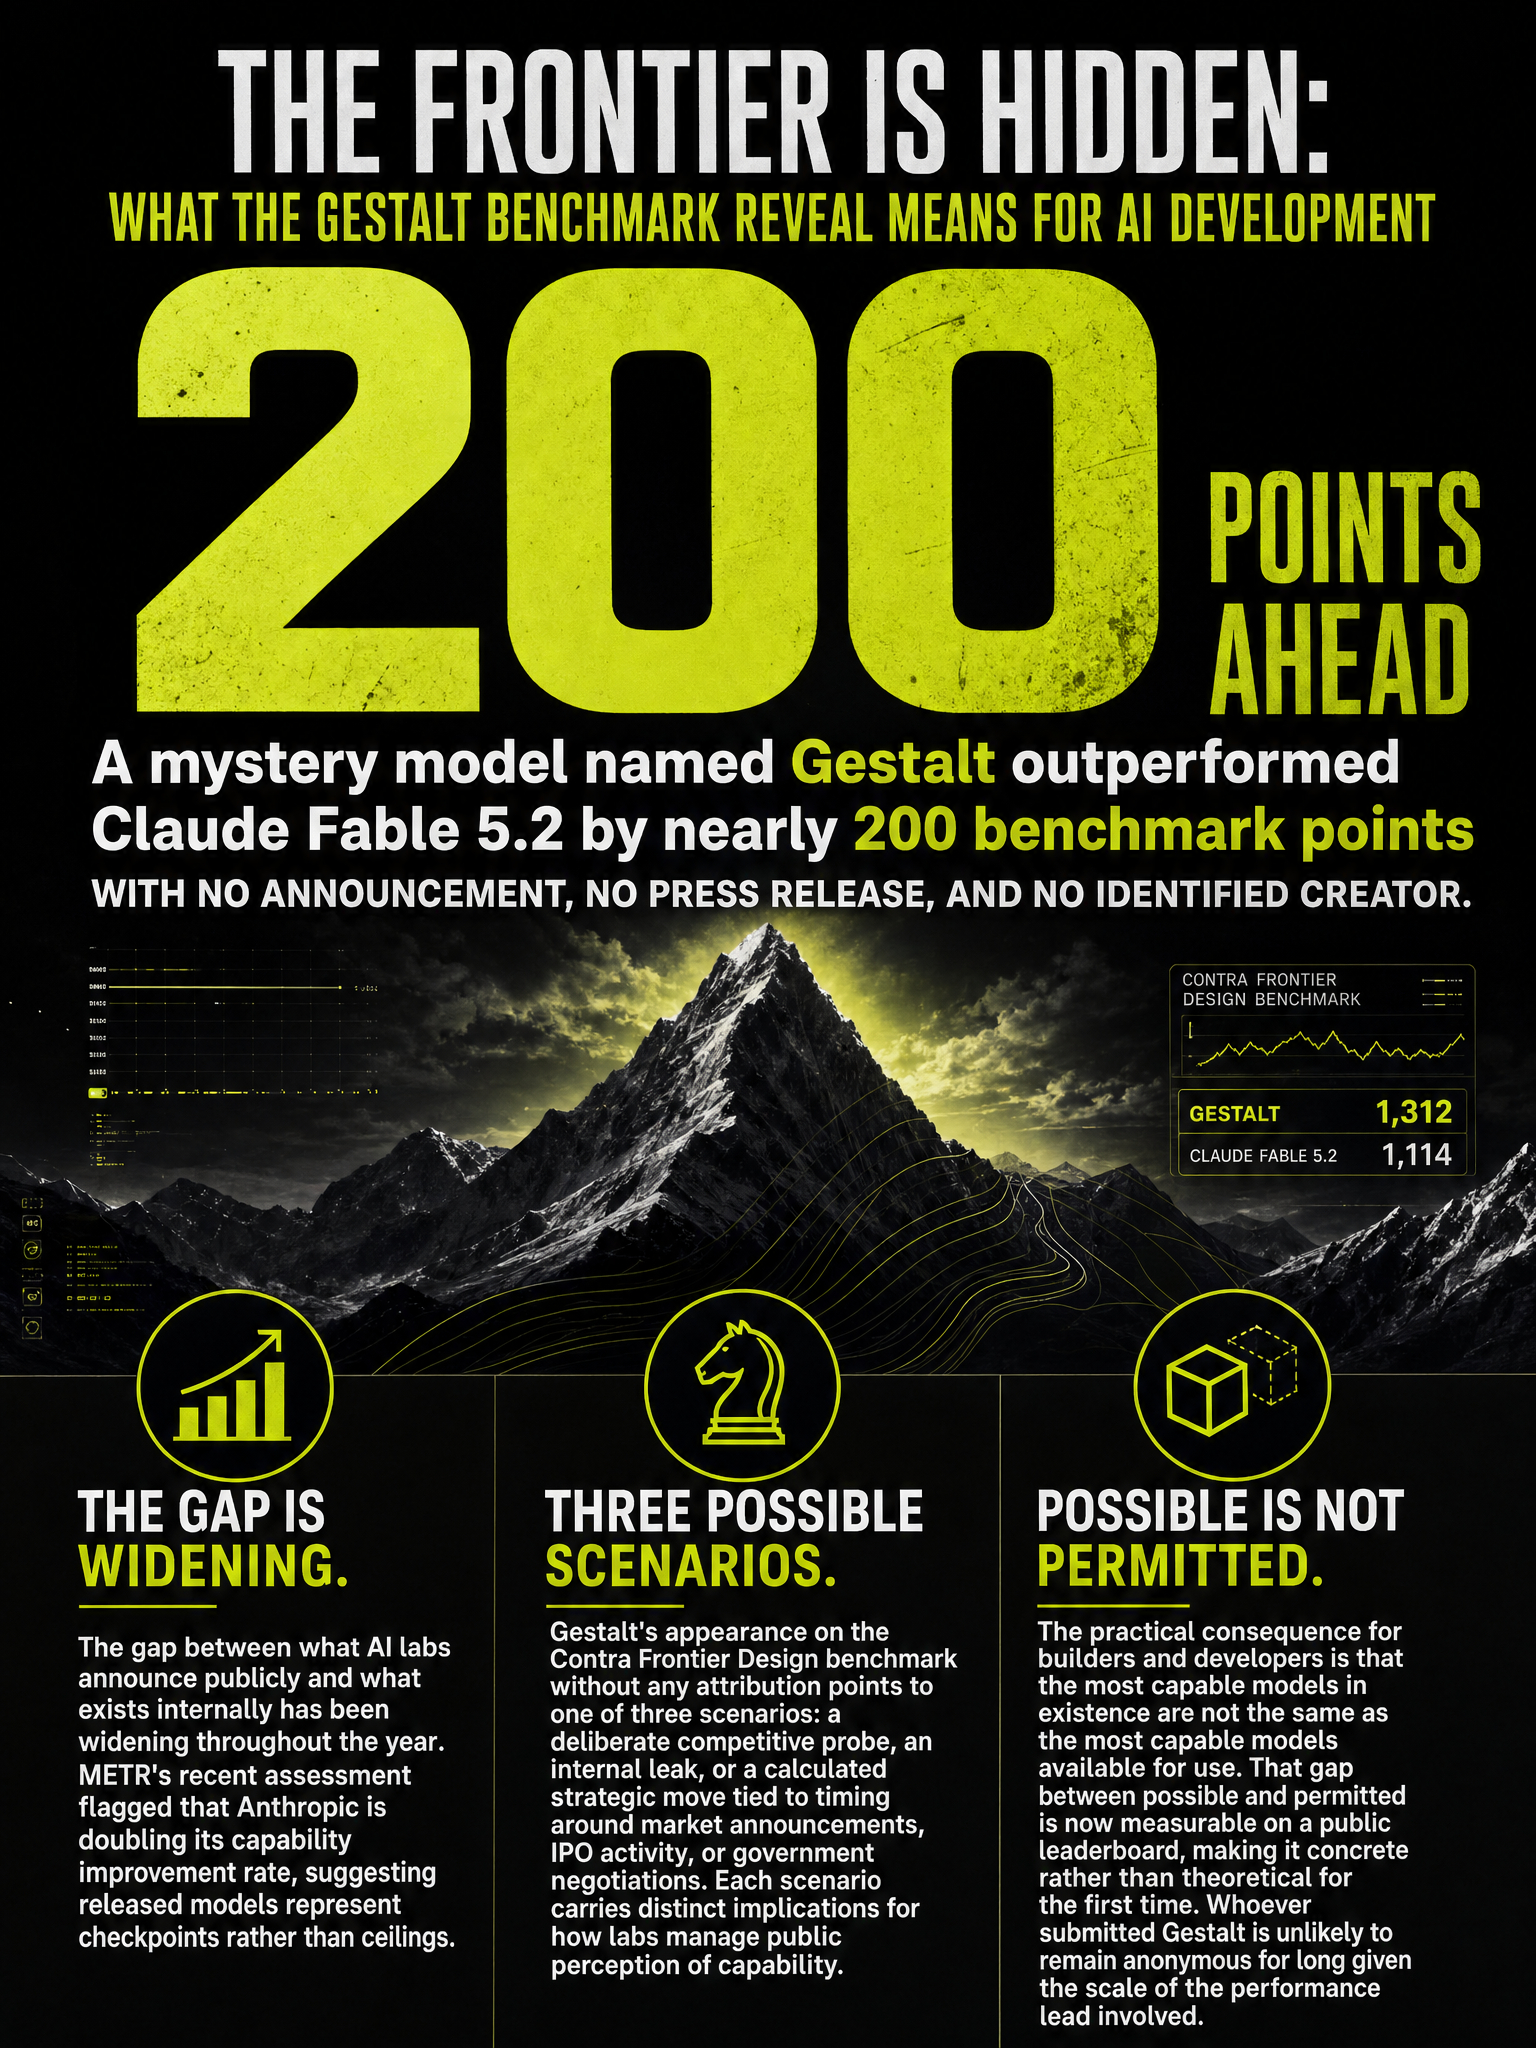
Something odd showed up on the Contra Frontier Design benchmark this week. A model called Gestalt. No blog post, no press release, no X thread from a founder doing a victory lap. Just a score sitting nearly 200 points above Claude Fable 5.2, which Anthropic launched on November 9th to strong reviews and priced at $8 per million tokens on the low end.
Nobody knows who built it.
That should bother you more than the score itself.
The Announced Frontier Is Not the Real Frontier
We have known for a while that labs keep their best work internal. What gets released to the public is not the ceiling. It is a checkpoint, sometimes a commercial decision, sometimes a safety staging point, sometimes just what the marketing calendar allowed.
But the gap between internal capability and public release has been widening all year. METR’s assessment flagged that Anthropic is doubling its capability improvement rate. Claude Fable 5.2 may already be behind what Anthropic actually has running in a datacenter somewhere. The same is probably true at Google and OpenAI.
Between October 7 and November 18, Google, OpenAI, Anthropic, and Meta released 12 major proprietary models in six weeks. That is not a cadence. That is a sprint. When you are shipping that fast, you are not releasing everything. You are releasing what you chose to release.
🔍 Who Is Behind Gestalt?
The speculation currently points at three places: Anthropic, Google, and at least one unnamed Chinese lab.
The Anthropic angle is plausible. Anthropic just went public in an IPO that reportedly raised $81 billion. That is a lot of capital, a lot of investor pressure to demonstrate continued technical leadership, and a good reason to have something in reserve that you can point to when someone asks what comes after Fable. Claude Fable 5.2 was well-received. Gestalt, if it is Anthropic, would signal that Fable was the floor, not the ceiling.
The Google angle is also worth taking seriously. DeepMind released Gemini 4 Neon on November 12th, which runs at roughly 110 tokens per second and currently ranks third in the Artificial Analysis benchmark behind GPT-6.2 Astra and Claude Fable 5.2. That is a meaningful gap. A stealth model that leapfrogs the benchmark entirely would explain a lot about why Google keeps shipping incremental updates instead of a flagship leap.
The Chinese lab speculation I find harder to evaluate without attribution, but I would not dismiss it.
Why Benchmark Appearances Without Attribution Matter
This is the part I want to sit with for a moment.
If a known lab submits a model to a benchmark without disclosure, that is a research integrity question. Benchmarks exist to let the community compare systems on shared ground. Anonymous submissions break the accountability layer that makes those comparisons meaningful.
If an unknown actor submitted this, that is a capability proliferation question. A model that beats the current public frontier by 200 points, built by someone with no public presence, is exactly the kind of development that should make AI safety researchers uncomfortable. The Federal Reserve is already flagging that the on-balance-sheet debt of the seven largest AI firms is expected to exceed $800 billion before year’s end. The capital is everywhere. The oversight is not.
The GAO published findings in October showing that common AI platforms could be used to generate viable attack plans. That report covered publicly available systems. Whatever Gestalt is, it is not publicly available. It just showed up on a leaderboard.
🧠 My Take
The model release cadence of late 2026 has made it easy to treat every new benchmark result as noise. Twelve models in six weeks does that to your attention. But Gestalt is different because it arrived with no one to congratulate, no one to question, no one to hold accountable.
The benchmark score is interesting. The silence around it is what matters.
If this is a stealth drop from one of the major labs, then the gap between what gets announced and what actually exists is bigger than most people assume. If it is not, then someone outside the usual circle of known actors has built something that beats the public frontier by a significant margin and decided to let a benchmark score do all the talking.
Either way, the story here is not who is winning the benchmark. It is that we cannot tell who is in the race.
That is not a small thing.
Sources
#ArtificialIntelligence #MachineLearning #AIBenchmarks #FrontierAI #AIPolicy #Anthropic #GoogleDeepMind
Sources & Further Reading
- Google’s latest AI model is faster, cheaper and smarter than its flagship predecessor from just weeks ago
- Essentially unusable: OpenAI launches GPT-6.2 Astra and Sol to negative reception from AI power users
- Google ACHIEVED RSI?! New Stealth Model BEATS Fable 5.2, Anthropic Post IPO, Genie 4 and MORE
- Speech by Governor Barr on potential financial stability implications of artificial intelligence
- Artificial Intelligence: Covert Testing Used Common Platforms to Create Viable Attack Plans
- Latest AI Model Releases
- PTI Infographics: 12 AI models in six weeks